
HNSW (Hierarchical Navigable Small World)
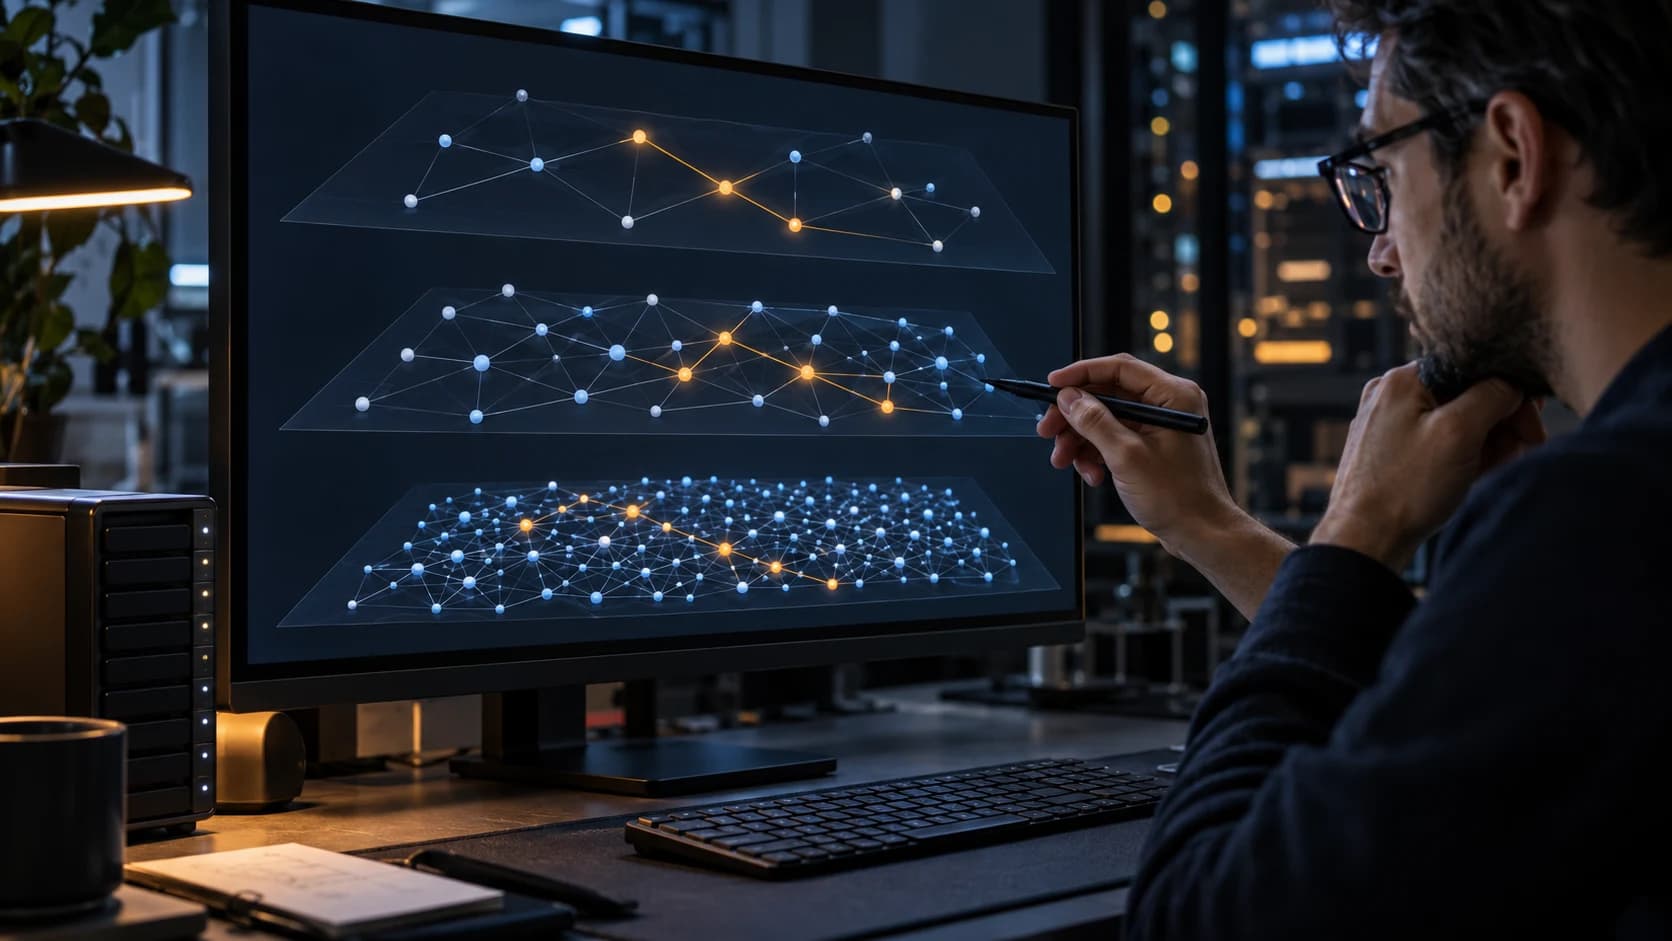
HNSW (Hierarchical Navigable Small World) is a graph index for approximate nearest-neighbour search: it finds vectors close to a query by walking a layered graph instead of comparing the query with every stored vector. Yu. A. Malkov and D. A. Yashunin introduced it in the 2016 paper Efficient and robust approximate nearest neighbor search using Hierarchical Navigable Small World graphs (arXiv 1603.09320). It is the index behind the hnsw option in pgvector, the only dense-vector index Qdrant currently uses, and the default vectorIndexType in Weaviate; FAISS also ships an HNSW index.
How it works
The paper describes a multi-layer structure of proximity graphs built over nested subsets of the data. Every vector lives in layer 0; each vector is also assigned a random maximum layer, drawn with an exponentially decaying probability, so each higher layer holds fewer vectors and longer links. The authors compare it to a skip list built from proximity graphs.
layer 2:  o───────────o───────────o        (few nodes, long hops)
layer 1:  o──o────o───o───o────o──o
layer 0:  o-o-o-o-o-o-o-o-o-o-o-o-o-o        (every vector)
A search starts at a fixed entry point in the top layer and moves greedily to whichever neighbour is closer to the query until it reaches a local minimum. It then drops one layer, restarts from that point, and repeats down to layer 0, where it keeps a list of the best ef candidates found so far. Because the number of links per node is capped on every layer, the paper reports logarithmic search complexity and O(N log N) construction, at least for relatively low-dimensional data. Inserting a vector runs the same search to find its neighbours, then links it to M of them, chosen by a heuristic that favours diverse directions and, per the paper, significantly helps at high recall and on clustered data.
The three tuning parameters
| Parameter | What it controls | Raising it | Documented defaults* |
|---|---|---|---|
M |
Links created per vector per layer; layer 0 allows 2 × M |
Better recall on high-dimensional data; more memory | pgvector 16, Qdrant 16, hnswlib 16; Weaviate calls it maxConnections, default 32 |
efConstruction |
Candidate-list size while building | Better graph quality; slower builds and inserts | pgvector 64, Qdrant 100, Weaviate 128, hnswlib 200 |
efSearch (ef) |
Candidate-list size per query | Higher recall; slower queries | pgvector 40; Qdrant uses ef_construct unless set; Weaviate adjusts it dynamically by default |
- Defaults as documented on 29 September 2026: pgvector README for v0.8.6; hnswlib README on its master branch (latest release note 0.10.0rc2); the current Qdrant and Weaviate documentation, which carries no version number on the pages cited.
How each behaves, per the official documentation:
Mis the main memory lever. The paper calls it the only meaningful construction parameter left to the user, suggests a range of 5 to 48, and says memory consumption is proportional to it. hnswlib's guide gives a reasonable range of 2 to 100, says 12 to 48 is fine for most use cases, and suggests 48 to 64 for high-dimensional data such as word embeddings at high recall. The paper found 2 ×Ma good cap for layer-0 links, and Weaviate documents the same rule.efConstructiononly affects build time and graph quality. The paper reports that beyond a point it adds little search performance for significantly longer construction; hnswlib says the same, and suggests measuring recall withefequal toefConstruction: below 0.9 there is room for improvement.efSearchis the knob you can change per query without rebuilding. hnswlib notes it cannot be lower thank, the number of results requested. In pgvector it isSET hnsw.ef_search.
When you change M, hnswlib says ef and efConstruction have to be updated too, and suggests estimating the new efConstruction by keeping the product M × efConstruction roughly constant: doubling M, for example, points to roughly halving efConstruction.
Memory
HNSW stores the graph next to the full vectors. FAISS gives the memory as (d × 4 + M × 2 × 4) bytes per vector, where d is the dimension: 4 bytes per float32 component plus the links. hnswlib estimates the link overhead alone at roughly M × 8–10 bytes per element. By the FAISS formula, one million 768-dimensional vectors at M = 32 need 3,328 bytes each, about 3.33 GB (decimal) or 3.1 GiB in total, before any engine overhead (our arithmetic, not a vendor figure). The vector DB sizer estimates index memory for other sizes.
HNSW vs IVF vs exact (flat) search
| Flat (exact) | IVF | HNSW | |
|---|---|---|---|
| Results | Exact; FAISS calls it the only index that guarantees exact results | Approximate | Approximate |
| Memory | Vectors only, no overhead | Vectors (IVF-Flat) or compressed (IVF-PQ) | Vectors plus graph links |
| Training | None | Clustering needed first | None |
| Speed knob | None | nprobe / probes |
efSearch |
pgvector says HNSW has better query performance than IVFFlat in terms of speed-recall tradeoff, but slower build times and more memory. Because IVFFlat is trained on existing rows and HNSW is not, Supabase says it is safe to build an HNSW index as soon as the table is created. FAISS recommends HNSW when you have a lot of RAM or the dataset is small, and moves to compressed IVF variants as memory becomes a concern.
Deletes and updates
The original paper lists element updates and removal as future work. Implementations add them differently: hnswlib marks elements as deleted, omits them from results, and can reuse their slots for new inserts; Weaviate keeps tombstones and cleans them up periodically; pgvector relies on Postgres VACUUM, which it says can take a while for HNSW and runs faster after a reindex; FAISS states that its HNSW index does not support removing vectors.
When not to use it
- You need exact results. Use a flat scan; pgvector performs exact search by default, with perfect recall.
- RAM is the binding constraint and the engine cannot compress. Compressed IVF indexes store less per vector, but HNSW is not tied to full-precision vectors either. Several engines combine it with quantization: Weaviate's HNSW index configuration has product (PQ), binary (BQ) and scalar (SQ) quantization options; Qdrant, whose only dense-vector index is HNSW, documents scalar quantization at 4x compression, binary at up to 32x and product at up to 64x; pgvector can build an HNSW index on half-precision or binary-quantized expressions.
- Your engine filters after the index scan and your filters are selective. This is a pgvector behaviour, not a property of HNSW itself. The pgvector README (v0.8.6) says filtering is applied after the index is scanned: with the default
ef_searchof 40 and a condition matching 10% of rows, only 4 rows match on average. It points to iterative index scans (starting with 0.8.0) and partial indexes as fixes. Qdrant documents a different design: a filterable HNSW index that extends the graph with additional edges based on indexed payload values, so filters apply during the graph search. It notes those edges are built per payload index, not for every combination of them, and offers the ACORN search algorithm (as of v1.16.0) for that case. - You need distributed search. The paper calls the loss of distributed search, versus basic NSW, an apparent shortcoming: every search starts at the top layer.
In the index
The Pinecone and Supabase profiles cover two managed options for vector search; Supabase runs Postgres with pgvector. Retrieval patterns on top are in Agentic RAG and the guide on connecting a local RAG pipeline with MCP. Figures on this page were checked against their sources on 29 September 2026.
Sources
- Yu. A. Malkov and D. A. Yashunin, Efficient and robust approximate nearest neighbor search using Hierarchical Navigable Small World graphs (layered proximity graphs with exponentially decaying level assignment; top-down greedy search; skip-list analogy; logarithmic complexity scaling; O(N log N) construction for low-dimensional data; neighbour heuristic; Mmax0 = 2M; M range 5–48 with memory proportional to M; efConstruction diminishing returns; updates/removal as future work; loss of distributed search): https://arxiv.org/abs/1603.09320
- nmslib, hnswlib ALGO_PARAMS.md (ef ≥ k; M range 2–100, 12–48 for most cases, 48–64 for high-dimensional data; memory roughly M × 8–10 bytes per element; M × ef_construction roughly constant; recall < 0.9 check): https://github.com/nmslib/hnswlib/blob/master/ALGO_PARAMS.md
- nmslib, hnswlib README, master branch, latest note 0.10.0rc2 (defaults M = 16, ef_construction = 200; mark_deleted and replace_deleted): https://github.com/nmslib/hnswlib
- Meta, FAISS wiki, Guidelines to choose an index (Flat is the only exact index; HNSW for lots of RAM or small datasets; memory (d × 4 + M × 2 × 4) bytes per vector; no training; no removal): https://github.com/facebookresearch/faiss/wiki/Guidelines-to-choose-an-index
- pgvector README, v0.8.6 (exact search by default; HNSW on halfvec and binary_quantize expressions; HNSW vs IVFFlat trade-off; m = 16, ef_construction = 64, ef_search = 40 defaults; post-index filtering example; iterative scans from 0.8.0; VACUUM on HNSW): https://github.com/pgvector/pgvector
- Qdrant, Indexing documentation, retrieved 29 Sep 2026 (HNSW is the only dense vector index; m: 16, ef_construct: 100 defaults; ef by default equal to ef_construct; filterable HNSW with payload-based edges; ACORN as of v1.16.0): https://qdrant.tech/documentation/concepts/indexing/
- Weaviate, Vector index configuration, retrieved 29 Sep 2026 (vectorIndexType defaults to hnsw; PQ, BQ and SQ options; maxConnections 32, layer 0 up to 2 × maxConnections; efConstruction 128; dynamic ef; tombstone cleanup): https://docs.weaviate.io/weaviate/config-refs/indexing/vector-index
- Supabase, HNSW indexes guide (safe to build HNSW immediately after table creation, unlike IVFFlat): https://supabase.com/docs/guides/ai/vector-indexes/hnsw-indexes
- Qdrant, Quantization guide, retrieved 29 Sep 2026 (scalar 4x, binary up to 32x, product up to 64x compression): https://qdrant.tech/documentation/guides/quantization/
In the Fathom index
Vector databases in the index. Matched on each item's own record and sorted A–Z, not by merit.