
Local AI Hardware / Entry tier
Ryzen 5 + RTX 4060 Ti Build
Entry-tier DIY build for local AI: an AMD Ryzen 5 CPU paired with an NVIDIA GeForce RTX 4060 Ti (16 GB VRAM) and 64 GB of system RAM. Runs small models such as Phi-4-mini (3.8B) and Gemma 3 4B at roughly 90 tokens/s — the lowest-cost path in this index to useful local inference.
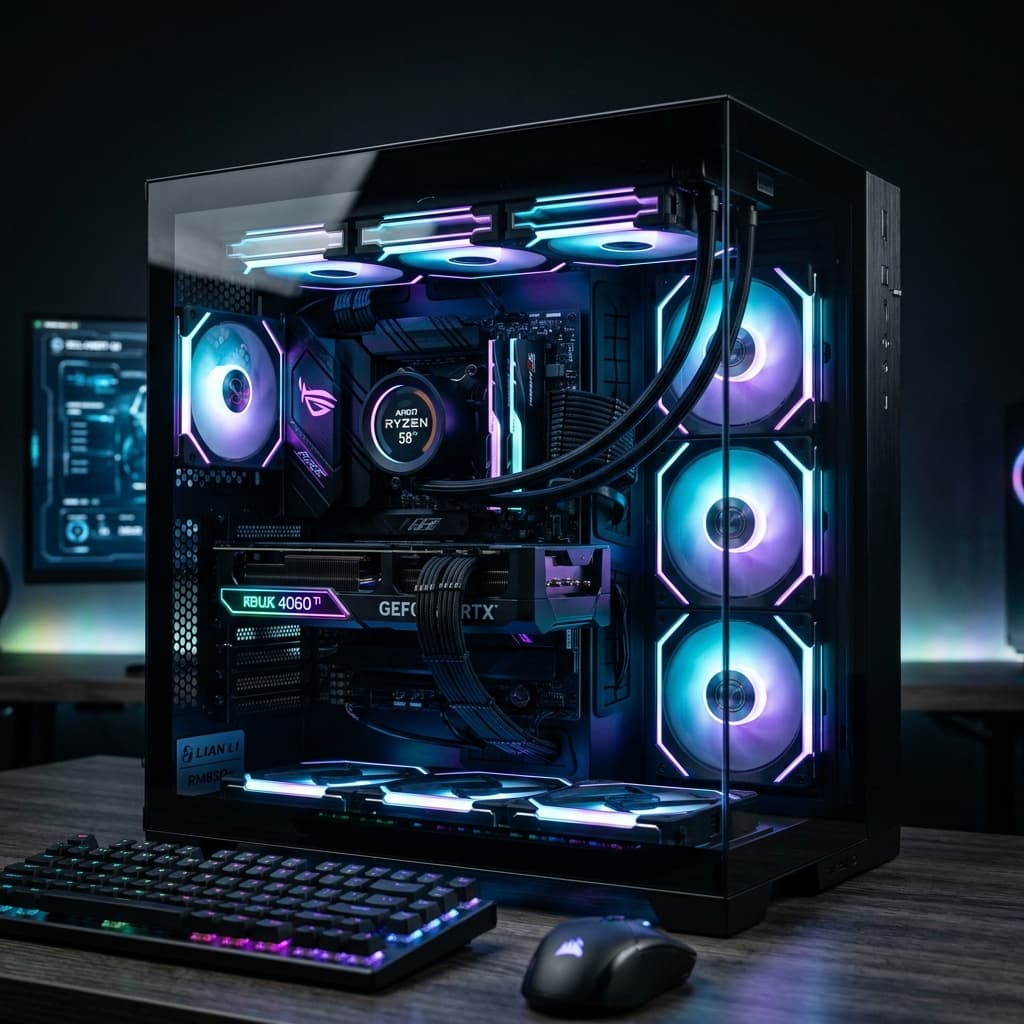
- CPU
- AMD Ryzen 5
- GPU
- NVIDIA GeForce RTX 4060 Ti
- RAM
- 64 GB
- VRAM
- 16 GB
The decision
Where it wins
- 16GB VRAM at entry-level pricing
- Accessible upgrade path
- Low power draw (160W GPU limit)
Where it doesn't
- Limited to 8B/14B models for fast inference
- Memory bandwidth restricts larger batch sizes
Specifications
Structured product data, grouped by system.
Core hardware03
| CPU | AMD Ryzen 5 |
|---|---|
| GPU | NVIDIA GeForce RTX 4060 Ti |
| Runs | Phi-4-mini (3.8B), Gemma 3 4B |
Memory & compute02
| RAM | 64 GB |
|---|---|
| VRAM | 16 GB |
AI & acceleration01
| Throughput | ~90 tok/s |
|---|
Read the record
The 16GB variant of the RTX 4060 Ti is the most economical entry point into CUDA-accelerated local AI. It provides enough VRAM to comfortably run and fine-tune models in the 8B to 14B parameter range, making it the default recommendation for budget-constrained setups.
The 16GB RTX 4060 Ti is the most economical entry into CUDA-accelerated local AI. Paired with a Ryzen 5 and 64GB of system RAM, this build runs small models like Phi-4-mini and Gemma 3 4B at around 90 tokens/second, and comfortably handles 8B–14B models for everyday use.
Why it is the default budget pick
16GB of VRAM at entry-level pricing is the key number — enough to run and even fine-tune (with QLoRA) models in the 8B–14B range without spilling to system memory. The 160W GPU power limit keeps the build cool, quiet and cheap to run, and the platform leaves an obvious upgrade path.
The limits
- Fast inference tops out around 14B. Larger models load but crawl.
- Memory bandwidth restricts batch sizes, so this is a single-user machine, not a small server.
Who should buy
Anyone starting with local AI experimentation, and people who mainly want to run Llama 3 8B-class models locally and reliably. If you already know you want 30B+ models, start with a 24GB card instead.
Frequently Asked Questions
Who is Ryzen 5 + RTX 4060 Ti Build for?↓
What are the drawbacks of Ryzen 5 + RTX 4060 Ti Build?↓
What does Ryzen 5 + RTX 4060 Ti Build do well?↓
What is the Fathom Layer design score for Ryzen 5 + RTX 4060 Ti Build?↓
Alternatives to consider
See all alternatives →Memory on record
- Another option Threadripper Pro + Dual RTX 4090 Build
48GB total VRAM for heavy inference
Explore its evidenceDesign score 9.2/10 - Another option GMKtec EVO-X2 (128GB)
128GB massive memory pool
128GB LPDDR5X 8000MHzDesign score 8.0/10 - Another option Nvidia GeForce RTX 3090 (Used)
24GB of GDDR6X memory for handling large datasets and complex scenes
Explore its evidenceDesign score 8.5/10
Further reading
Featured badge
Building this product? Add the badge to your site to show it’s in the index.
<a href="https://fathomlayer.com/compute/local-ai-workstations/ryzen-5-rtx-4060-ti-build" target="_blank" rel="noopener noreferrer"><img src="https://fathomlayer.com/fathom-badge.svg" alt="Featured on Fathom Layer" width="250" height="54" /></a>